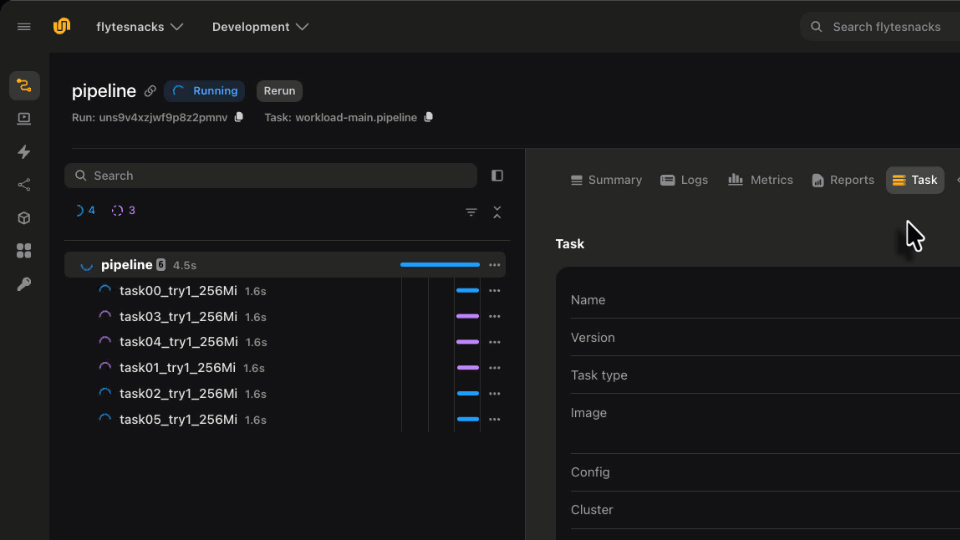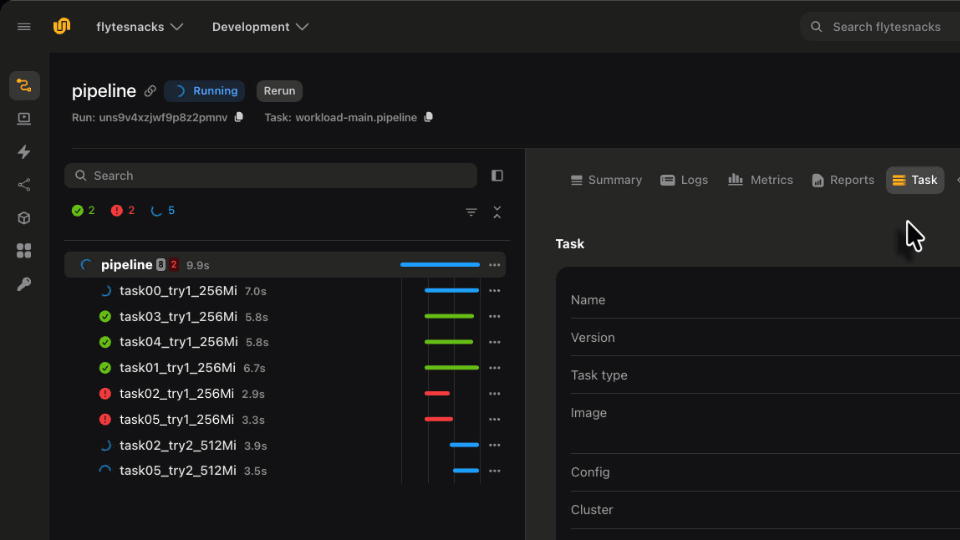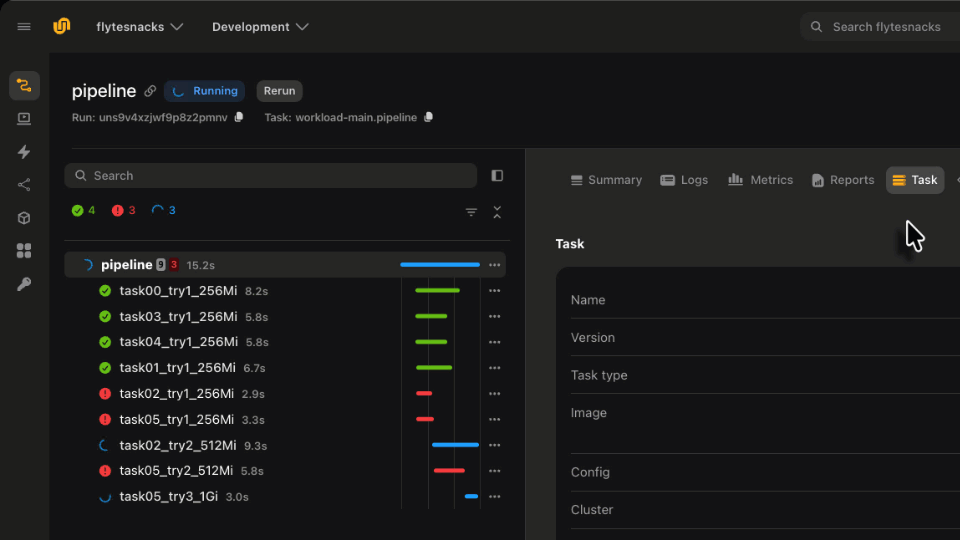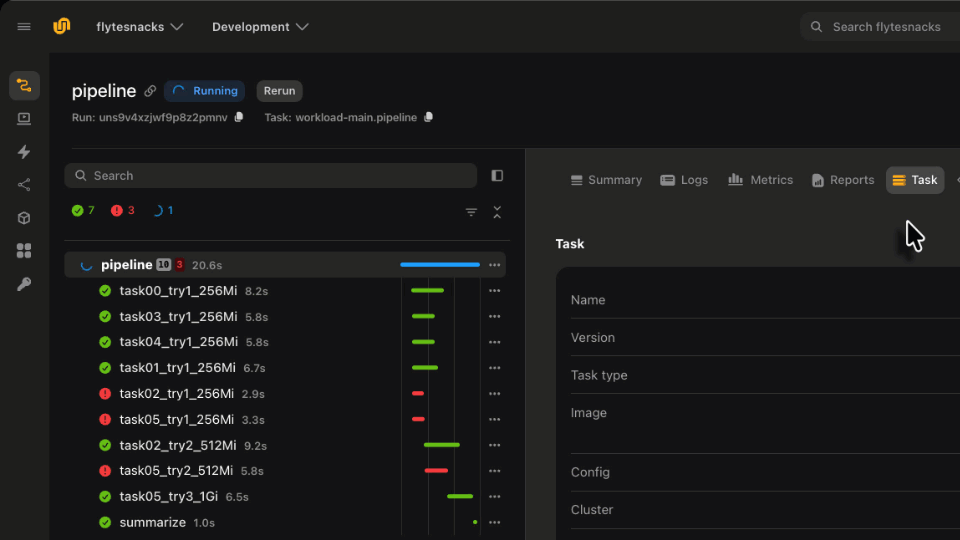
Except blocks can change the hardware.
Most runtimes hand you a stack trace. Union hands you a typed error and the ability to do something about it. Catch an OOMError and re-run the same task on a bigger box, in a try block you wrote. The runtime knows what compute exists and can provision more mid-run.
- Typed infrastructure errors OOMError, TaskInterruptedError, TaskTimeoutError, ImagePullBackOffError. Failures you can branch on.
- Resources changed at runtime .override(resources=...) re-runs the same task with different memory, CPU, or accelerator.
- The policy is yours: Write the handler, share it as a helper, or let an agent control it with the same API.
Recover. Fork. Replay.
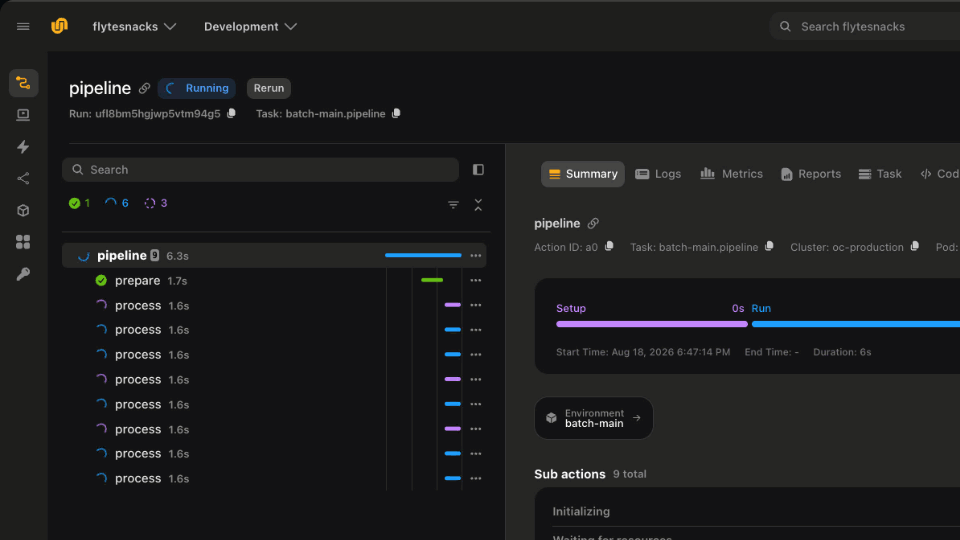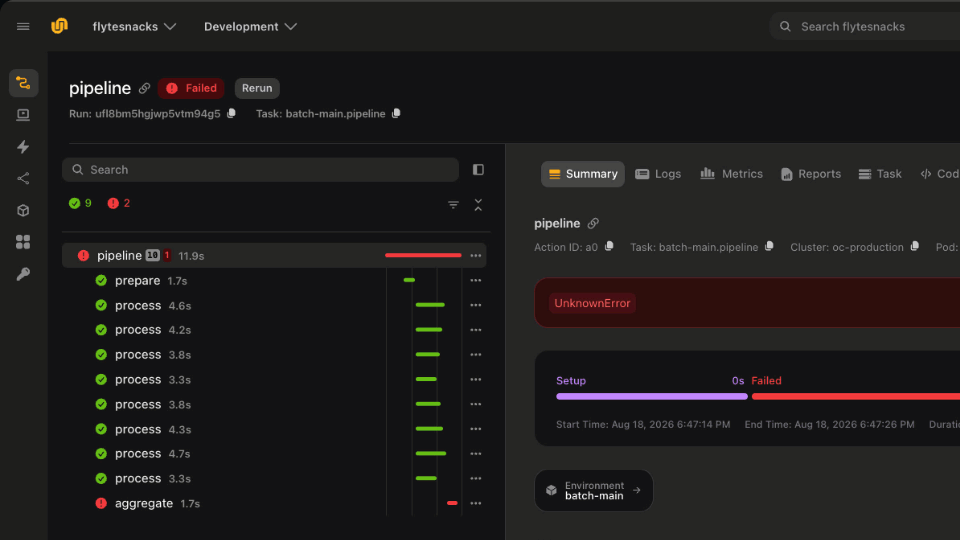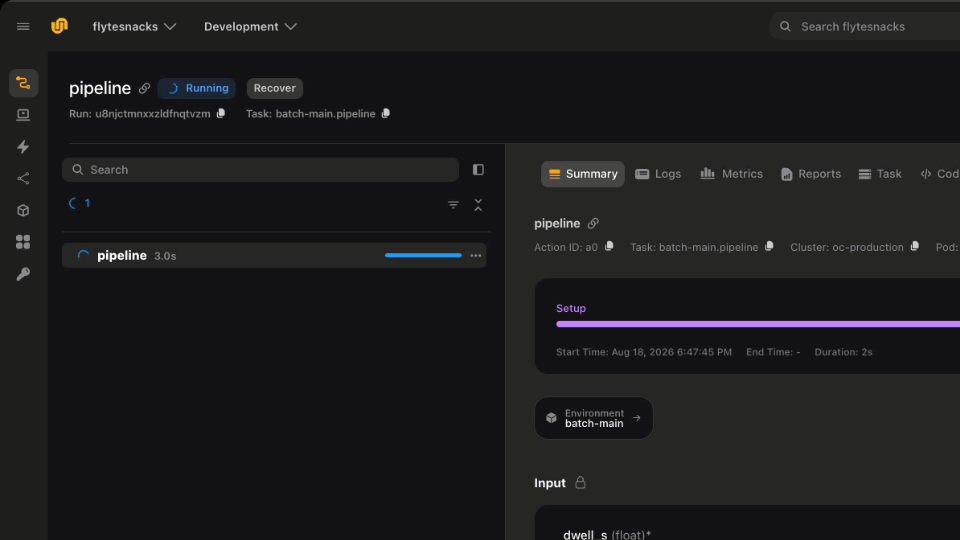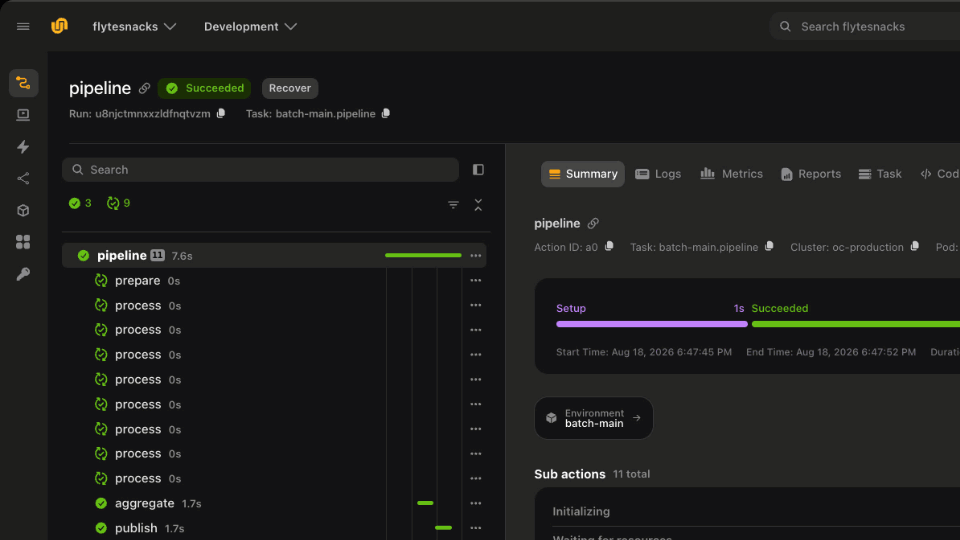
A retry that starts from the top is not recovery, it is the same run again with the same bill. Union records what finished as the run happens, outside the node doing the work. That record is what you resume from, fork from, or run again with new code.
- Recover what failed Point recover at a prior run. Steps that succeeded are reused, and only what failed or changed runs again, even without caching enabled.
- Fork from any step flyte.rerun starts a prior run again at the step you pick, with different code or inputs. Everything before it is reused.
- Replay with today’s code --rerun-from runs a prior run’s inputs against the code on your machine right now.
Outputs that outlive the run.
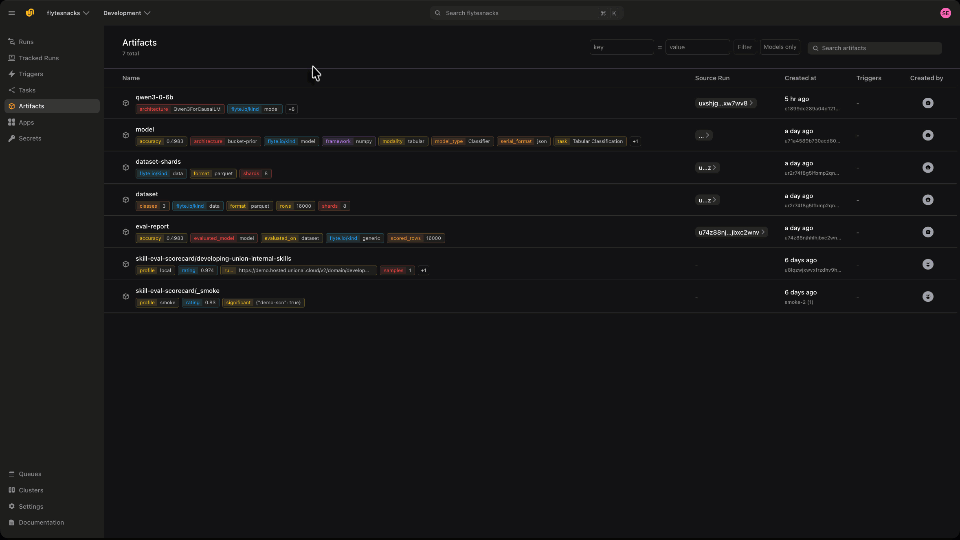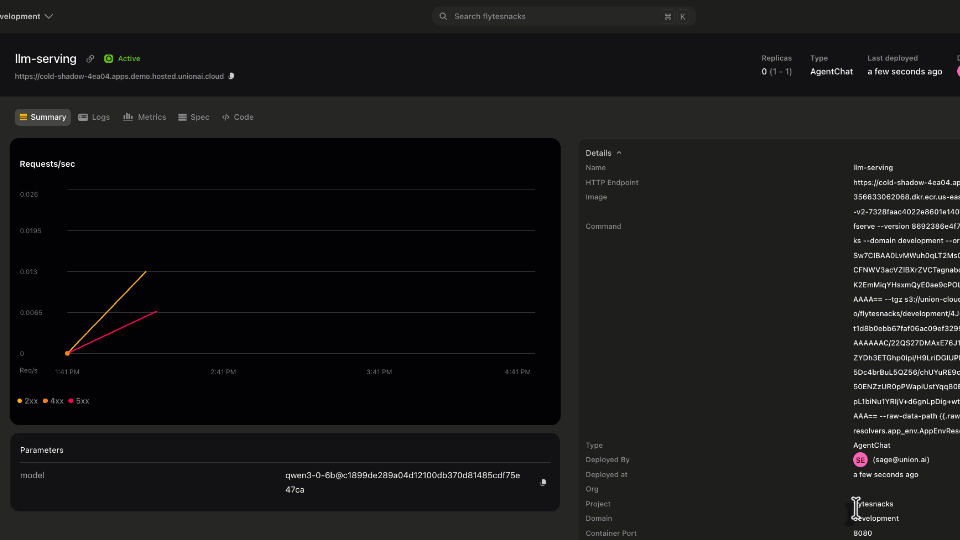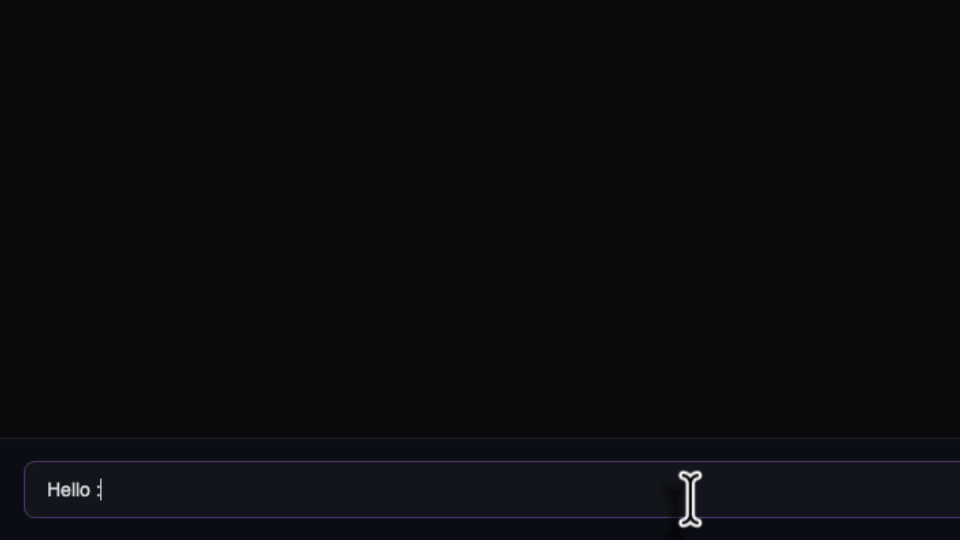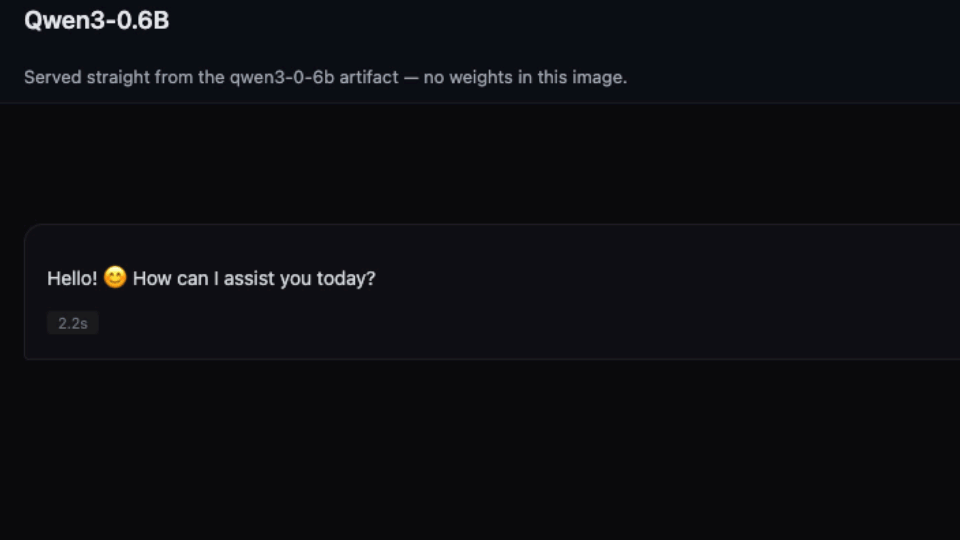
A pipeline’s output should not be a path you need to remember. Artifacts are typed, versioned values that persist past the run that made them, so a second workflow consumes the first one’s output without re-running it, and a new version can fire the next run by itself.
- Passed between workflows & Apps One pipeline’s output is another’s typed input, without re-running the producer.
- Versioned, not overwritten A new version is a new artifact, so a downstream run resolves to the exact input it used.
- Events, not polling flyte.OnArtifact fires a run whenever a new version of a named artifact is created.
Reproduce a run from months ago.
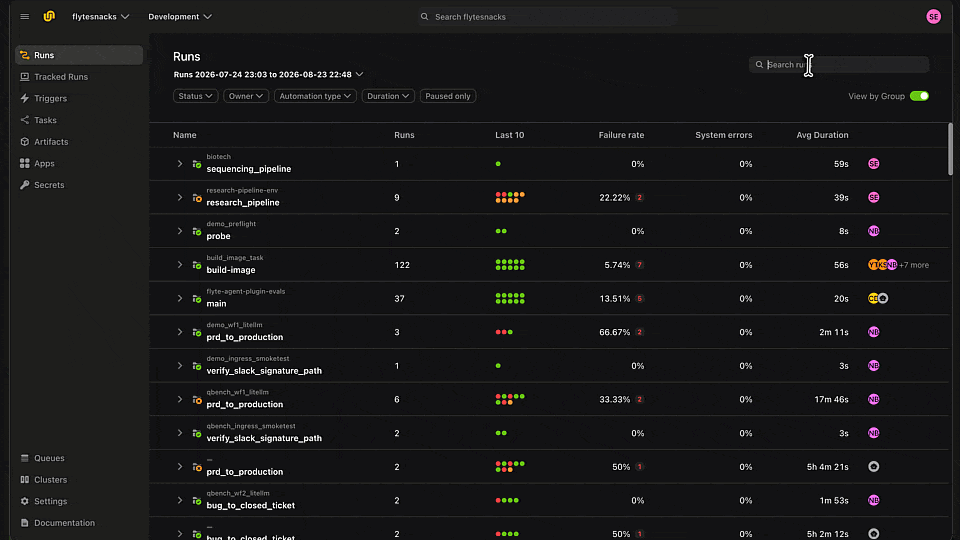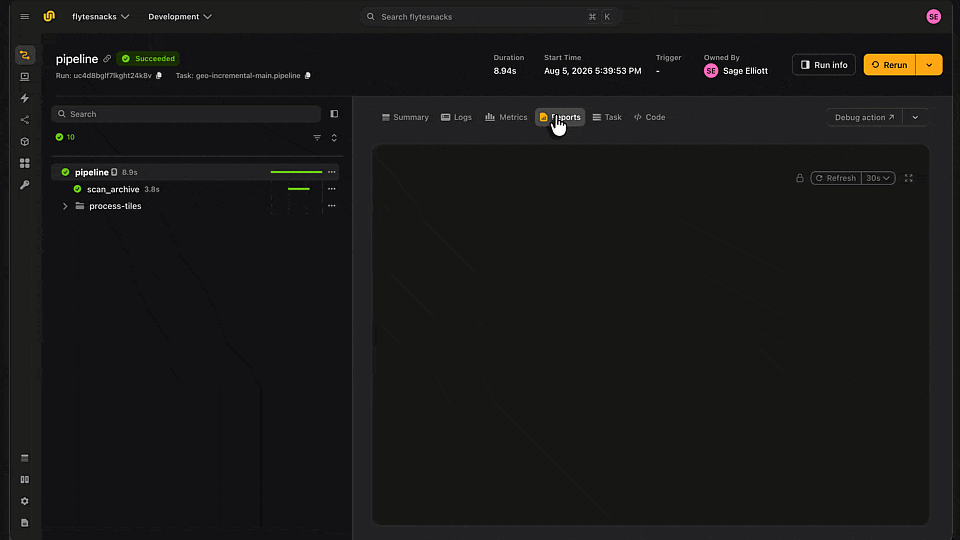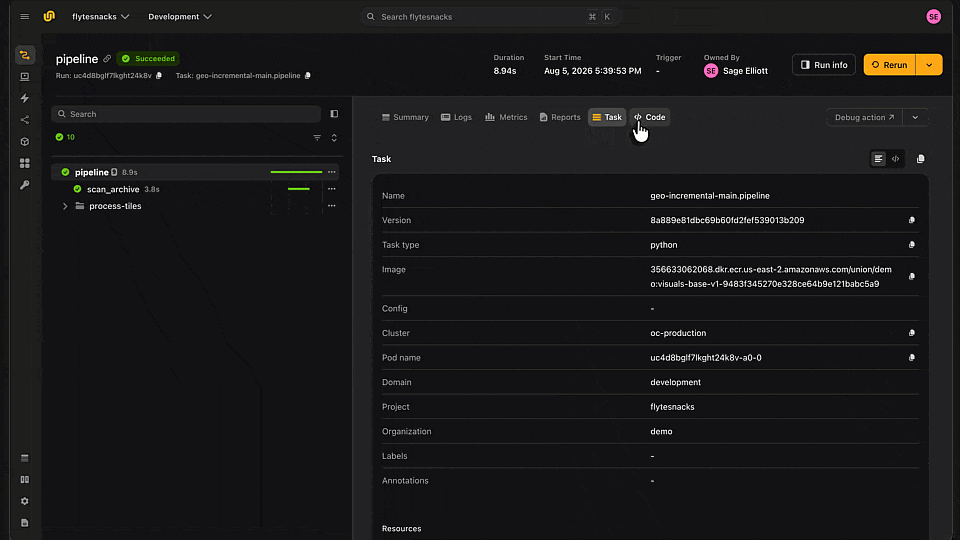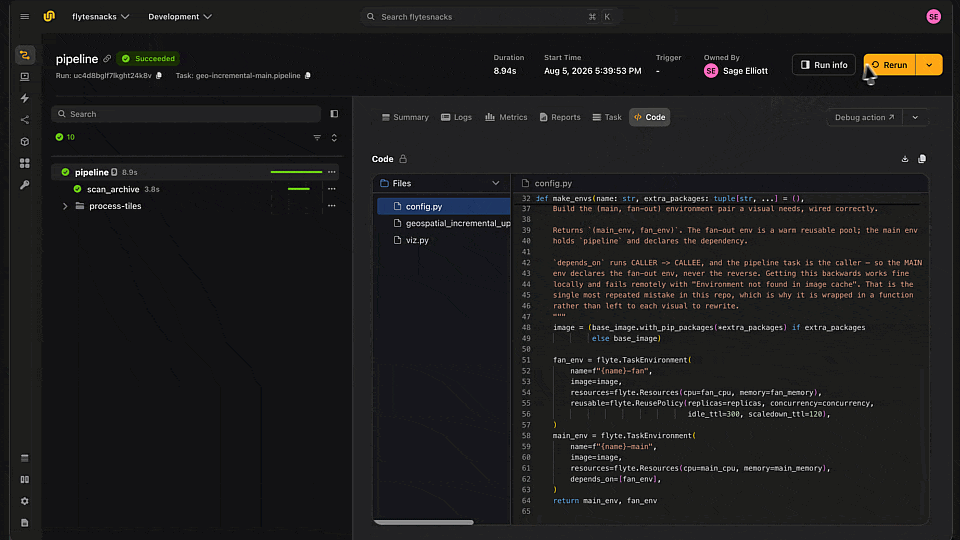
Every run keeps what it takes to reproduce a result: the code, the infrastructure it ran on, and the configuration applied to both. That is what makes a pipeline shareable rather than personal, and it is the same record an audit or a postmortem needs. For agent workloads it doubles as the trace of what the agent did.
- Inputs and outputs per run. Open an execution from months ago and see exactly what went in and came out.
- The code that ran, not the code today. Each run resolves to its own code bundle and container image.
- Observability for agents. Every step a non-deterministic workflow took is on the record, including the ones it chose itself.
Fan out on durable asyncio.
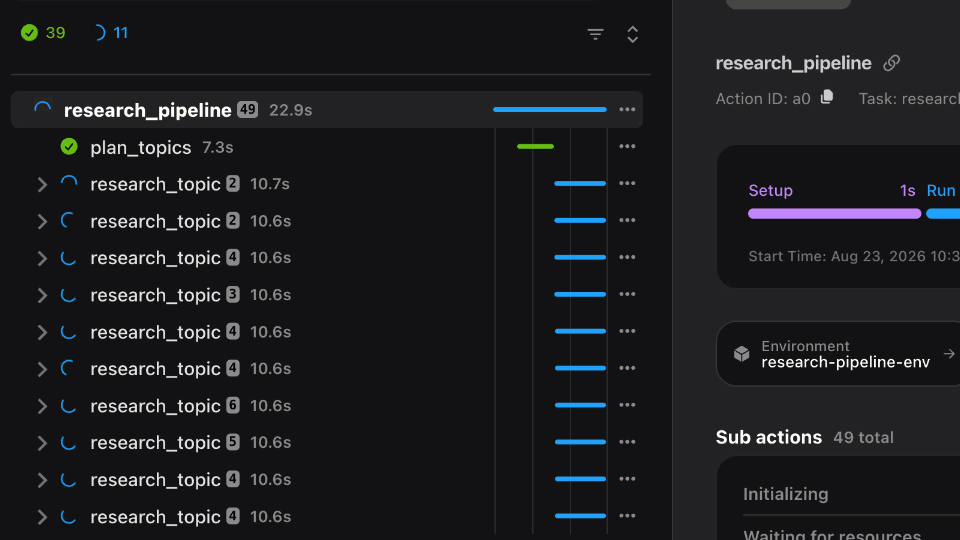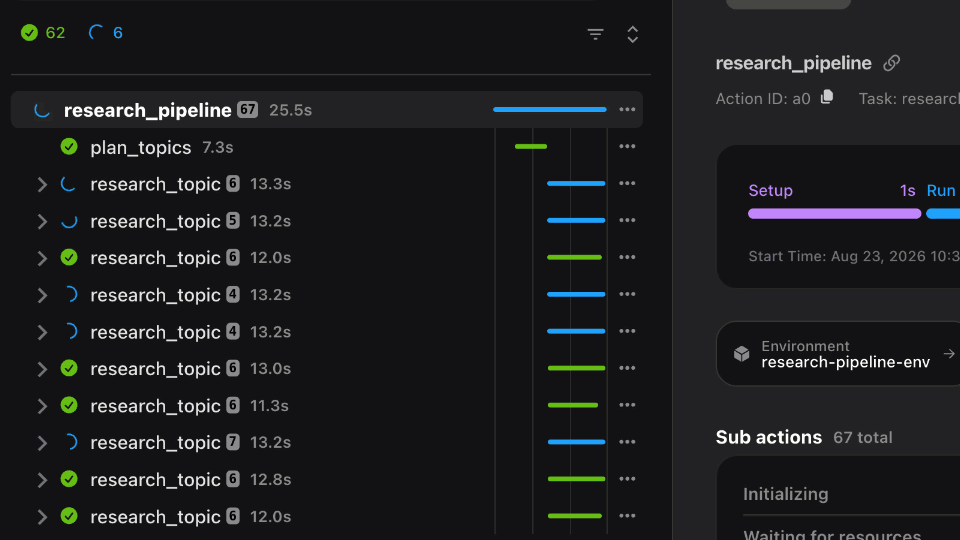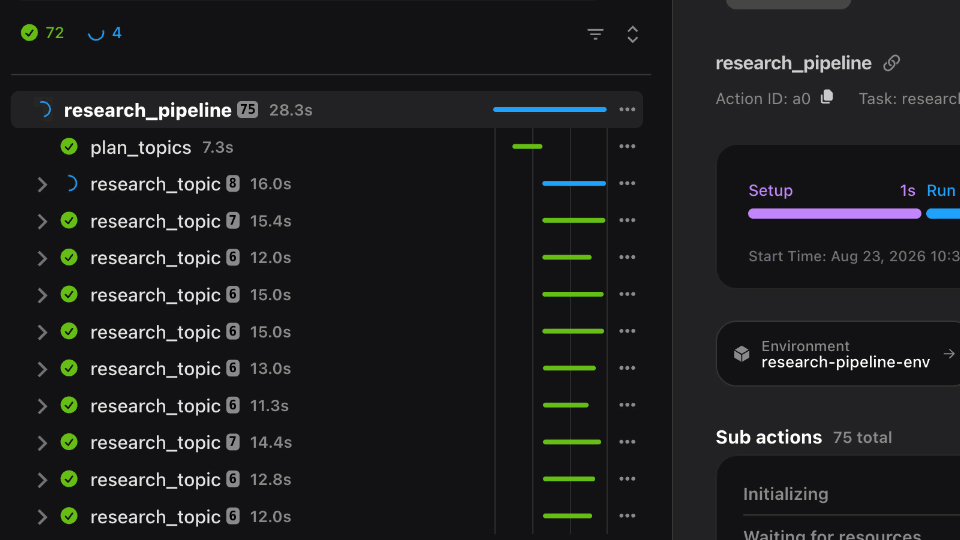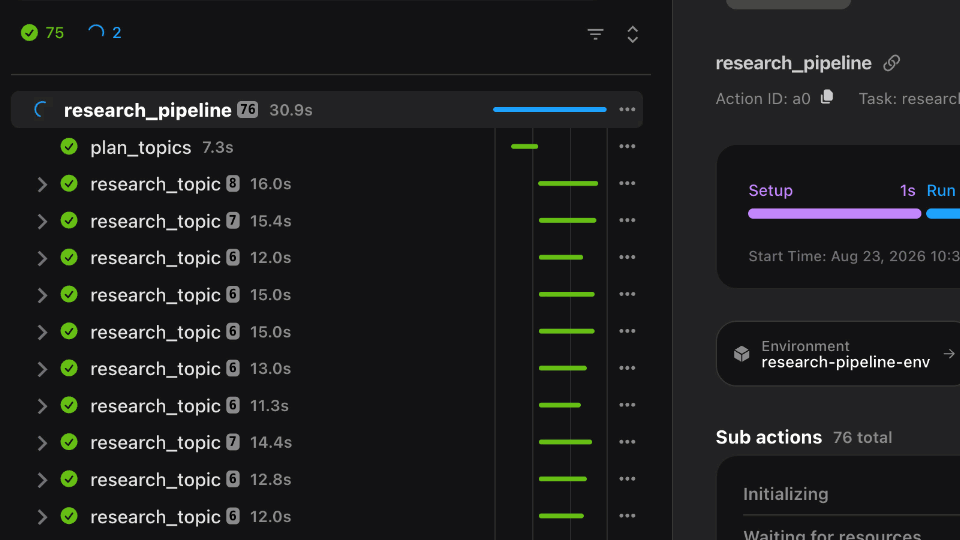
Fanning out is plain async. asyncio.gather when you want the whole set at once, flyte.map.aio when you want bounded concurrency over a long list. If the cloud takes a spot node back mid-run, that branch retries and the rest keep going.
- Concurrency you can cap. flyte.map.aio(fn, items, concurrency=500) bounds how many run at once, for a fan-out wider than the cluster.
- Retries with pacing. retries=5, or a RetryStrategy with exponential backoff so a flaky dependency gets time to come back.
- Built for spot. interruptible=True puts branches on spot nodes, the cheap ones a cloud provider can take back at any time. Losing one is expected here, not an incident.
Running where a lost run is expensive.
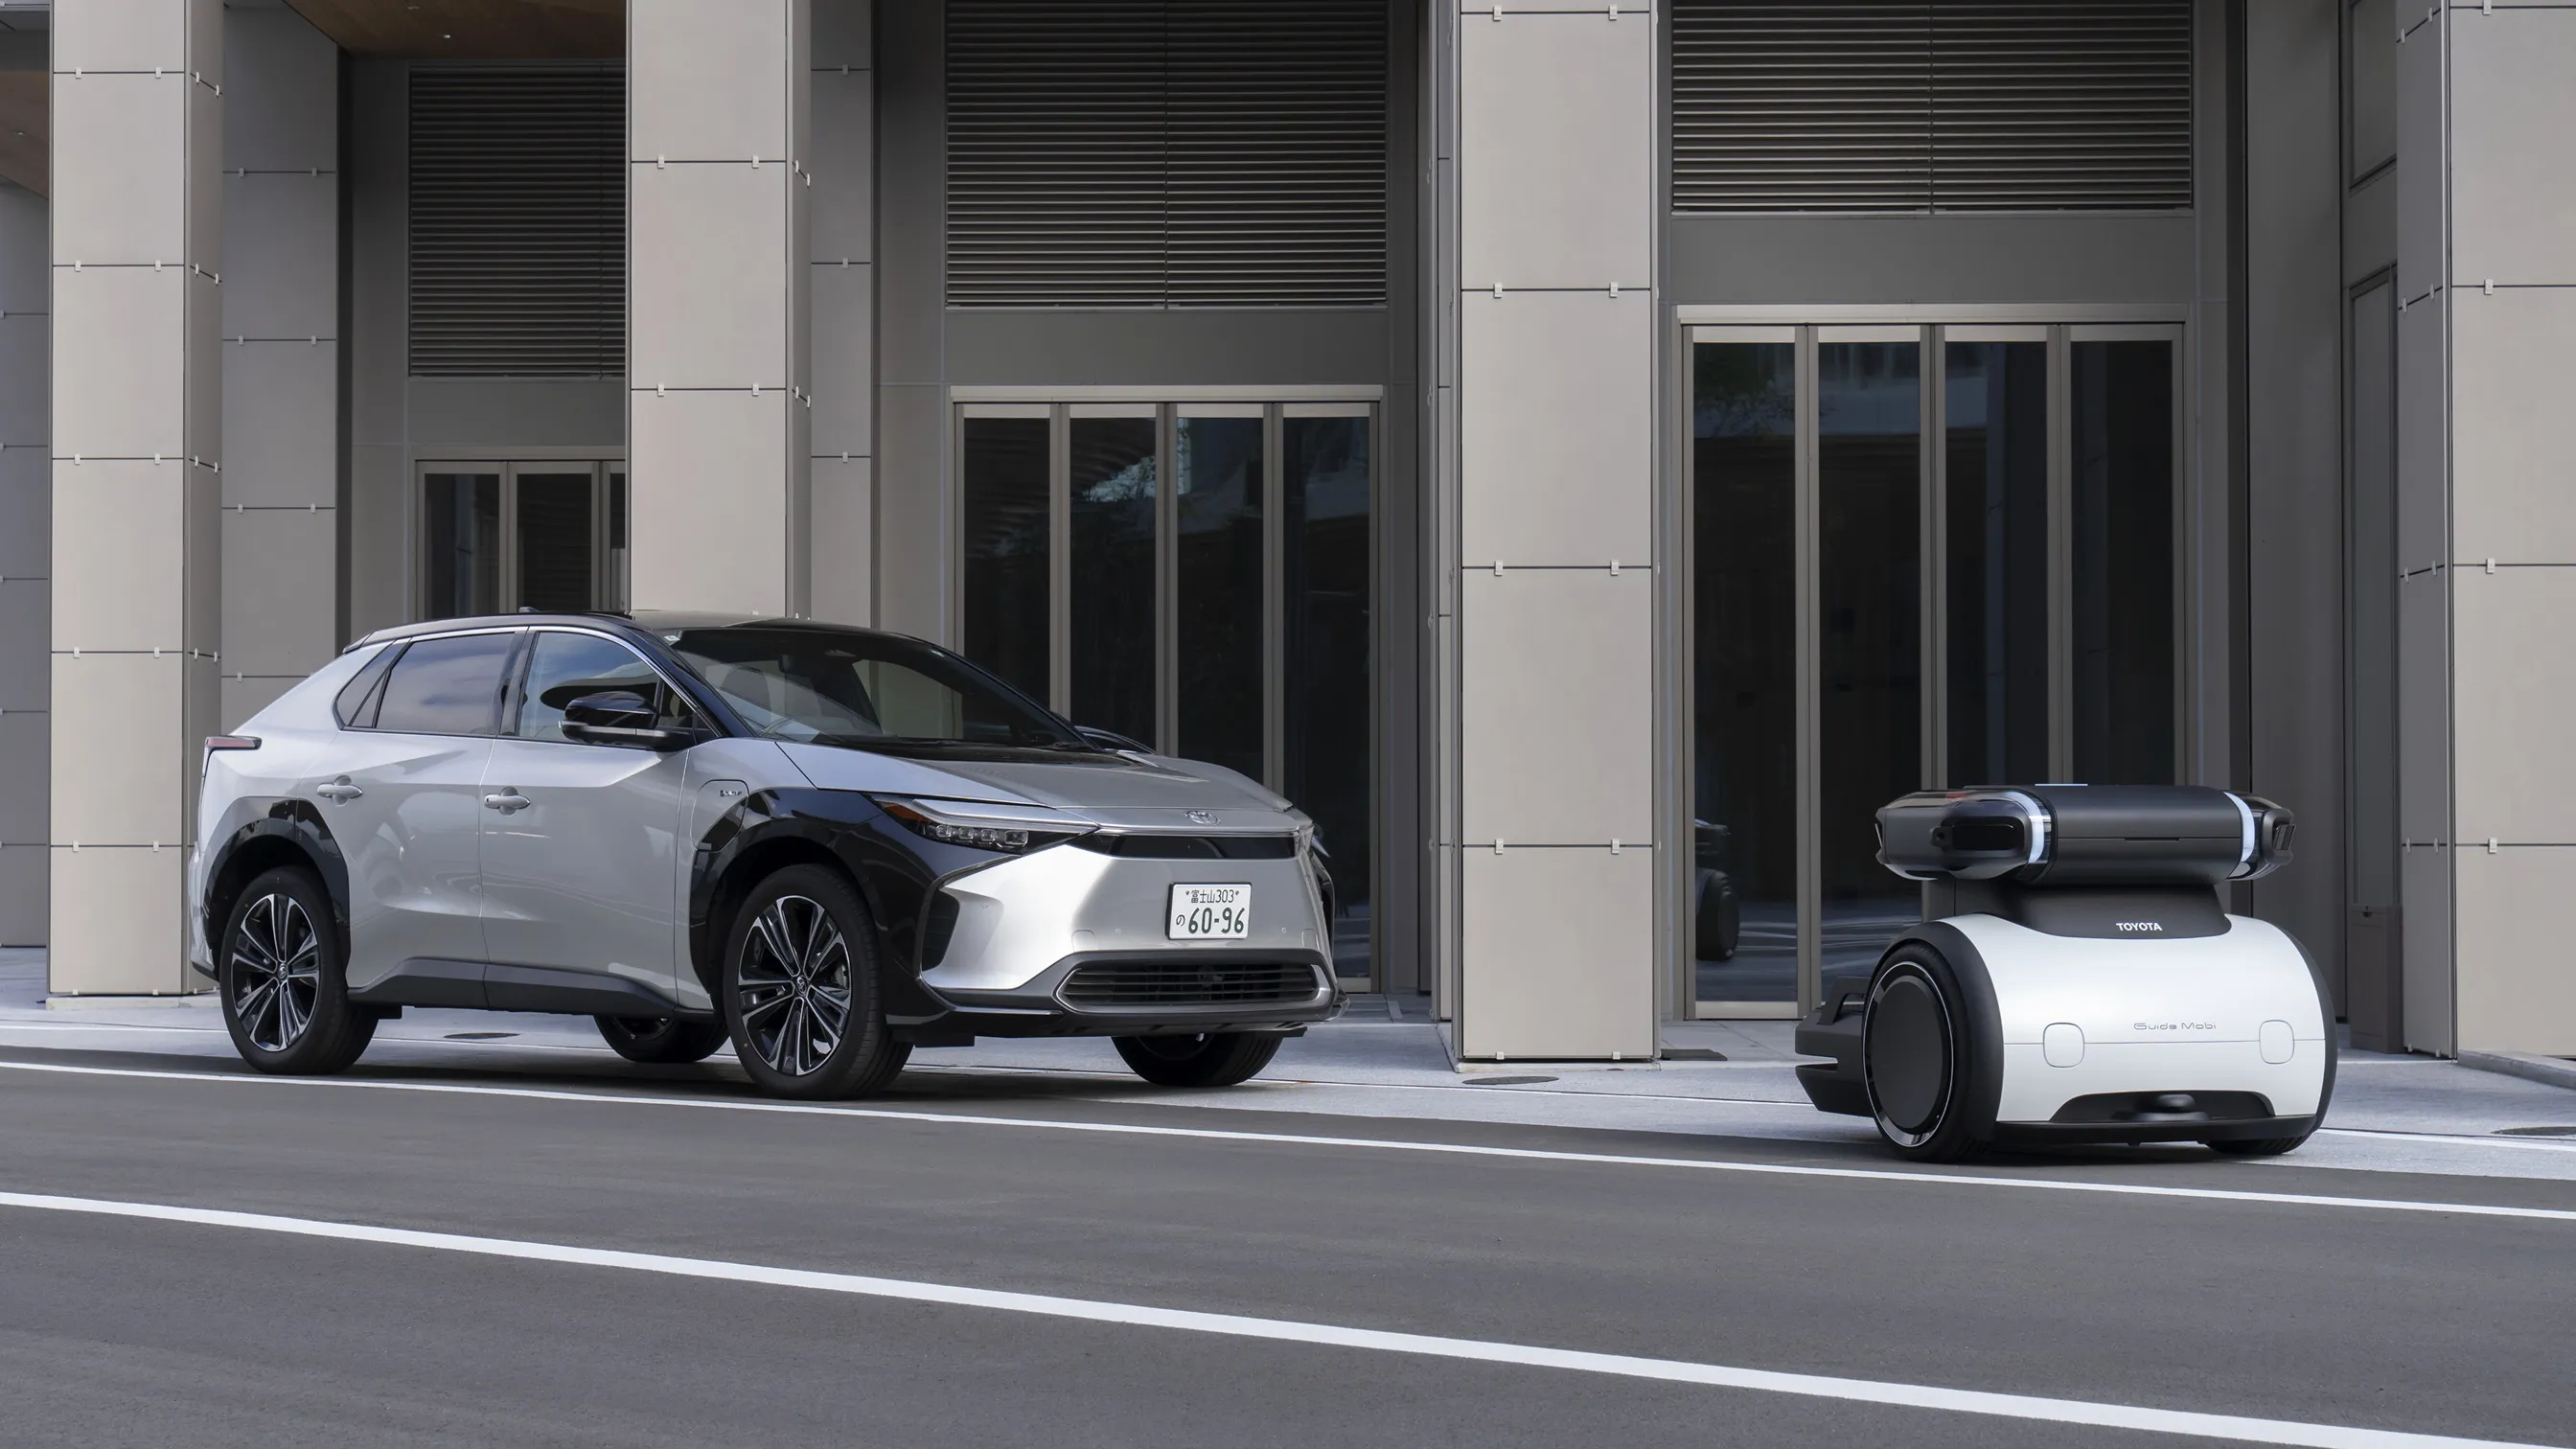
Autonomous driving, cancer therapy, and agentic research at catalog scale. Long runs on infrastructure large enough to fail constantly.
Open source at the core.
Union is built on Flyte, the open-source AI runtime we create and maintain under the Linux Foundation AI & Data.
companies using Flyte today
Flyte SDK downloads